Building a complete, production-ready SaaS with an AI coding agent
How BlackMesa designed, secured and shipped a full platform — zero-downtime deploys, real payments, passwordless sign-in — paired with an AI agent.
 BlackMesa
21/09/2026
Key elements
- Challenge — ship an enterprise-grade SaaS (reliability, security, compliance) with a small team, without blowing the budget or the timeline.
- Solution — human + AI coding agent (Claude) pair development, on a production-minded Symfony / Docker architecture from day one.
- Result — live platform: zero-downtime deploys, real recurring payments, passkey sign-in, sovereign object storage.
- Next steps — monitoring & alerting, managed backups, finishing the FR / EN / ES localisation.
Context and challenges
The context
- The company — BlackMesa, a software engineering studio: small teams, demanding client projects, a "real production" culture.
- The project — Show me the REX, a platform for publishing data/AI case studies (REX): a community media where companies and partners tell their project stories, with a client area, subscriptions and a back office.
- The challenge — reach a level most small outfits never reach (zero interruption, live payments, GDPR, performance) with a very small team.
- The team — one founder-developer, continuously paired with an AI coding agent that executes, suggests, tests and documents.
Choice of partner and solution implemented
A pair, not just a vendor
- The "partner" here is a human + AI duo: the human owns architecture and product decisions; the agent speeds up everything else — migrations, tests, refactors, documentation.
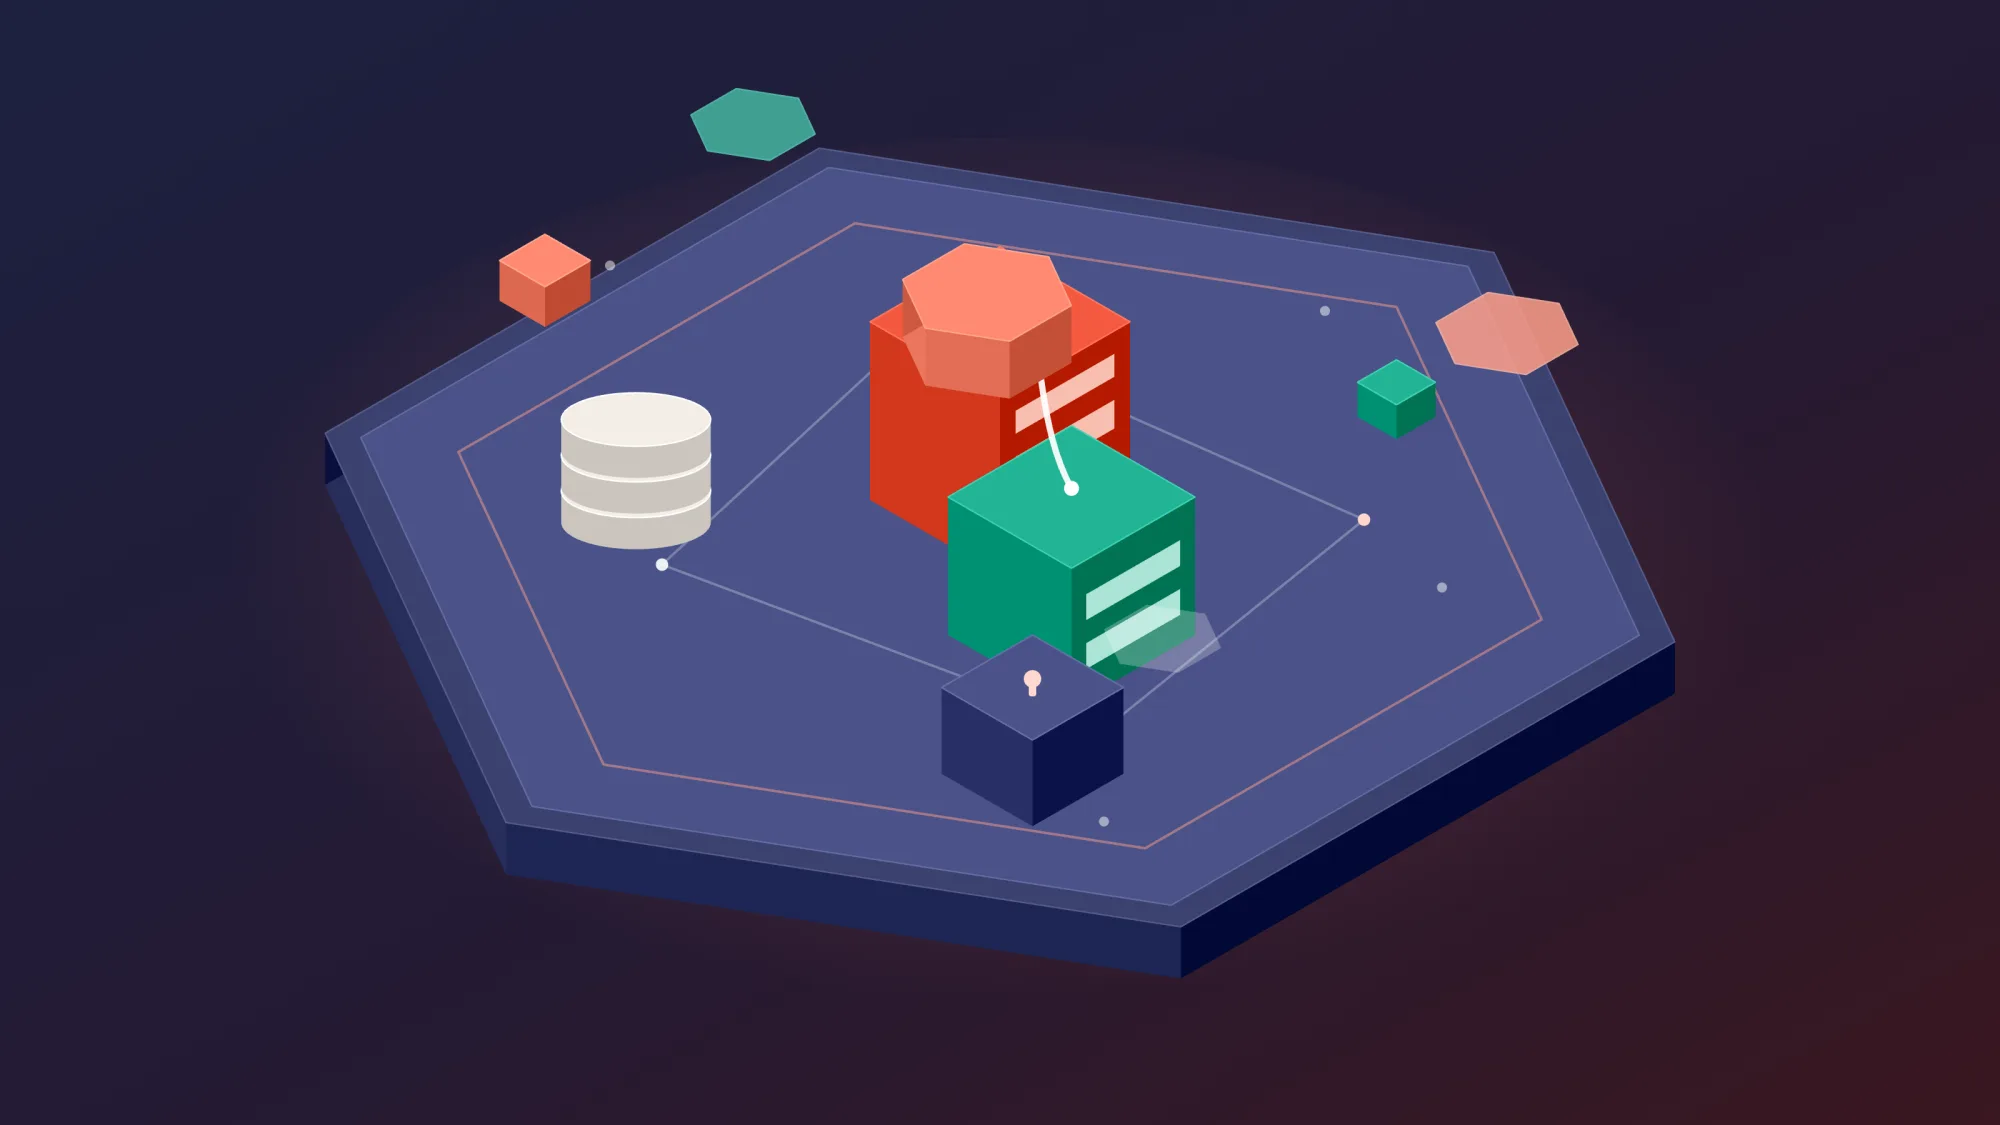
- The stack: Symfony 7.4 + FrankenPHP, fully containerised with Docker, PostgreSQL, Redis for sessions, Caddy at the edge.
- Sovereignty: object storage at OVHcloud (staying French) rather than a US hyperscaler.
- The structuring choice: a blue-green topology from the start, to deploy without ever cutting the service.
Testimonial
AI didn't replace engineering: it multiplied it. The hard decisions stay human — but on everything else, we move ten times faster.
Project timeline
Foundations worthy of production
It all starts with Docker: the same environment locally and in production, killing an entire class of "works on my machine" bugs. FrankenPHP serves the app, PostgreSQL stores the data, Redis holds the sessions. From day one, infrastructure was treated as a deliverable — not a chore left for the end.
An architecture that ages well
The business core is isolated from the rest: a DDD (domain-driven design) approach in a hexagonal(ports & adapters) style, so the logic depends neither on the framework nor on the database. Reads and writes go through CQRS (command / query buses via Messenger), which makes heavy work asynchronous and the code testable. Concretely: we add a feature without breaking the others, and test it without booting the whole site.
Deploying without ever going down — no gas factory
Zero-downtime deployment has an industry "default" answer: Kubernetes driven by ArgoCD (GitOps). It's powerful — and it's also a cluster to operate permanently, upgrades, a complexity that assumes a dedicated team. With a small team, we made a deliberate choice: a leaner, just-as-zero-downtime approach — blue-green.
Two versions of the app run in parallel ("blue" and "green"); a Caddy proxy switches traffic from one to the other with a graceful reload, once the new version is healthy. With sessions living in Redis, nobody is logged out during an update. Database migrations are written expand / contract to stay compatible during the switch. Concrete result: we deploy in the middle of the day, with no felt downtime — and without the operational burden of an orchestrator.
An asynchronous media pipeline
When an author publishes a video or an image, page rendering must never wait. Images are converted to WebP, videos transcoded to H.264 with a thumbnail — all in the background, via a message queue handled by a dedicated worker. The page shows immediately, and the "clean" media replaces the original as soon as it's ready.
Pages that respond in a snap
The foundation is built for speed: a persistent application server (FrankenPHP), an HTTP cache at the edge that serves public pages almost instantly, pre-optimised media and no blocking storage call at render time. The visitor gets a fast display — and, incidentally, a leaner one.
Security and privacy by default
Modern passwordless sign-in (passkeys / WebAuthn) and two-factor for administration. On the audience side, analytics are privacy-friendly: no session forced on anonymous visitors, lightweight beacon measurement, and an HTTP cache at the edge to handle load.
Getting paid for real
The platform handles real subscriptions: direct debit via GoCardless, VAT correctly applied, and sync to the accounting tool. Going live with payments changes everything: there's no more "sandbox", every detail counts.
Responsible tech
Sobriety was a design criterion, not a badge. Images are systematically optimised (WebP, resized to the size actually displayed): less bandwidth, less storage, lighter pages for everyone. Development environments are shut down every evening, to avoid consuming needlessly at night. Hosting is sovereign (OVHcloud, in France). And the infrastructure is deliberately frugal: blue-green mobilises two instances for the duration of a switch, where an orchestrator would run permanently. Choices that shrink the footprint without taking anything away from the service.
The role of AI, no myth
The coding agent didn't "write the site on its own". It multiplied one engineer: proposing implementations, writing tests, running migrations, documenting, spotting pitfalls. The hard decisions — architecture, product trade-offs, what goes live — stayed human. It's exactly this balance that let us move fast without sacrificing solidity.
Results and next steps
- Before / after — from an empty repo to a full production platform in a few months: public multilingual site, client area, subscriptions, back office.
- Measurable gains — no felt downtime on deploys; media pages shown without a blocking storage call; leaner server image and a cleaned-up disk; near-daily releases.
- Near-instant rendering of public pages (HTTP cache at the edge + persistent application server), even under load.
- Next steps — monitoring & alerting, managed backups, error supervision, and finishing the FR / EN / ES translation.
Best practices
- Treat infrastructure as a deliverable from day one (dev = prod via Docker).
- Write backward-compatible migrations (expand / contract) to deploy without downtime.
- Keep slow calls (object storage, external services) out of render paths.
- Validate every infra change before applying it — render the config, never deploy blind.
- Version and automate everything: commit → CI → deploy.
- Treat observability — logging, tracing, alerts — as a deliverable, never an option.
- Make digital sobriety a design criterion (media weight, resources used), not a marketing line.
- Isolate the business core (DDD / hexagonal) and split reads from writes (CQRS): features that add without breaking the rest.
Points of caution
- An AI agent can suggest a risky action: guardrails are essential — systematic human review on anything touching production, a backup before any change.
- Object storage is a point of failure: short timeouts and graceful degradation, never a blocking call at render time.
- Operational debt gets paid: cleanup (disk, volumes, unused images) must be planned from the start, not discovered on a saturation day.
- Sovereignty ≠ free simplicity: sovereign storage has its specifics (per-object permissions) to absorb in code.
Comments
No comments yet. Be the first to comment!
You must be signed in to add a comment.
Dated at the model level
- Model
- Claude Opus · v4.8
- Review by
- 22/03/2027
Tags
REX produced by